Cohort-component vs. housing unit method for population projection
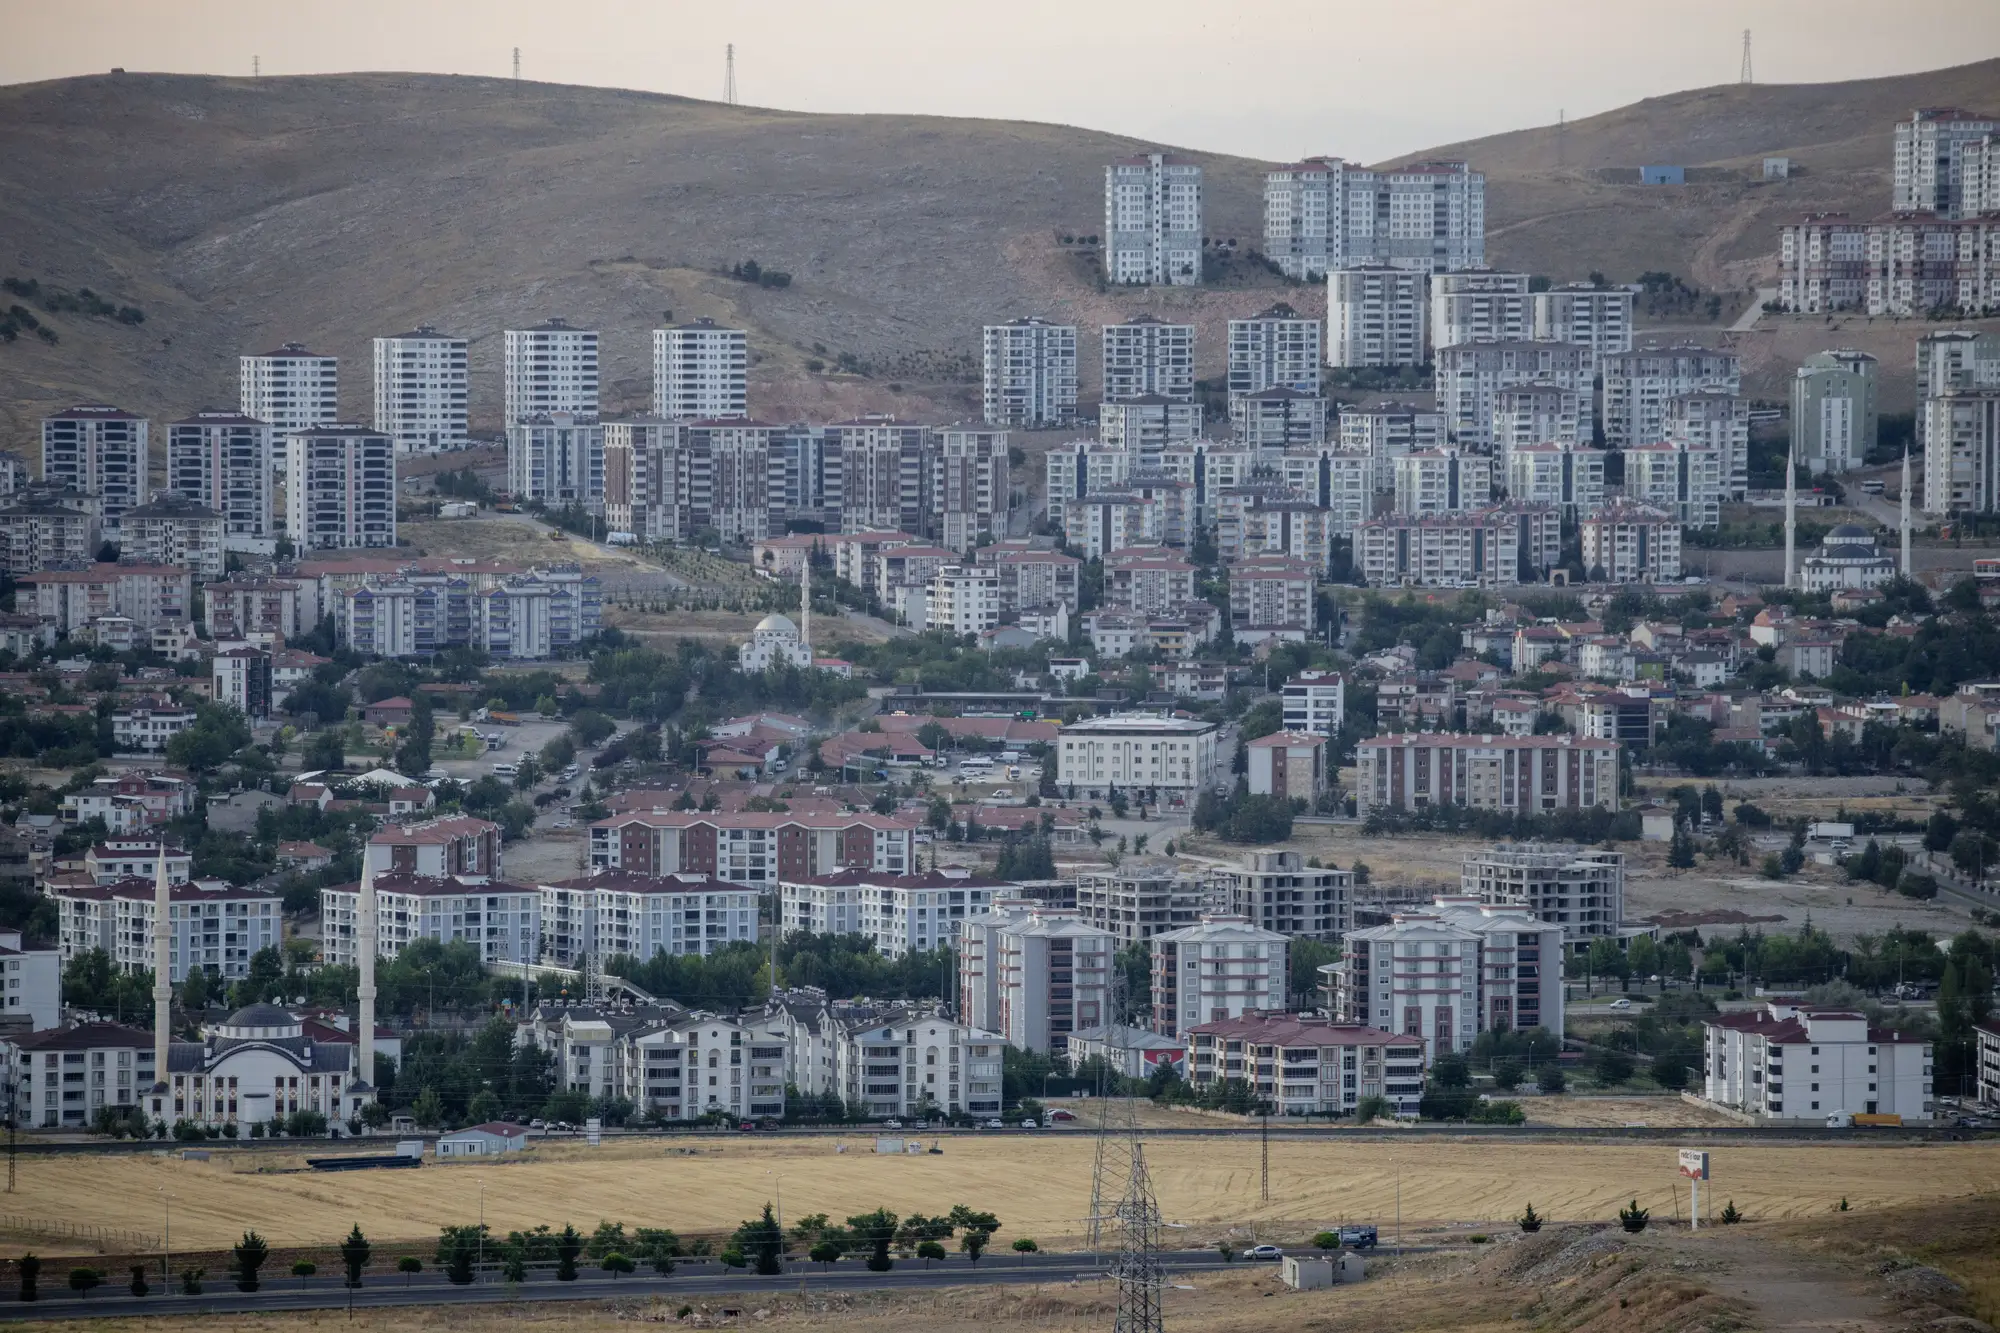
Both methods answer the same question, how many people live somewhere between two censuses, but they start from different inputs and fail in different places. If you're estimating for a national total, the choice barely matters. If you're estimating for one district that's added housing stock faster than the last census could track, it matters a lot.
What each method actually counts
Cohort-component takes the last census population, broken out by age and sex, and ages it forward. Each cohort gets a fertility rate, a survival rate, and a net migration assumption, and you sum the cohorts back up to a total. It's the standard approach for national and regional projections because vital registration (births, deaths) is usually reliable enough to drive it, and because age structure matters for things like school enrollment or pension planning downstream.
The housing unit method skips age structure entirely. Population equals occupied housing units times average household size, plus whatever's living in group quarters, dormitories, barracks, institutional housing. The two inputs that make or break it are a current count of housing units and a household size figure, which usually comes from the last census or a recent household survey.
Where each one breaks in a fast-growing district
Cohort-component's weak point, at sub-national scale, is migration. National fertility and mortality rates are reasonably stable and well measured. Internal migration into one district is not. Most statistics offices don't run a migration register fine enough to say how many people moved into a specific fast-growing district last year, so the model falls back to distributing regional migration proportionally. That assumption is exactly wrong for a district growing faster than its region, which is the district you're usually being asked to estimate.
The housing unit method's weak point is the housing unit count itself. If that count comes from the last census, and the district has been adding subdivisions, infill, or informal structures every year since, the denominator is stale before you've finished the calculation. The method is only as current as its structure count.
That's also what makes it the more workable choice at district scale, once you can refresh that count. It runs on a current structure count, an occupancy or vacancy rate, and a household size figure, skipping the district-level vital rates and migration model that most offices can't support with the data they have. The household size figure can reasonably hold over from the census if housing type in the district hasn't shifted much.
Combining the two
Offices that do both usually run cohort-component at the national or regional level, to keep the total consistent with vital statistics, and use a housing-unit allocation to split that total down into fast-changing districts. The regional number sets the ceiling, the district-level housing count sets the distribution.
Building height matters more here than it sounds like it should. A structure count alone treats a single-story house and a four-story walk-up as one unit each, flattening real differences in household density across a district. Pairing the structure count with a current building-height layer lets you adjust household size by structure type, applying a different figure to walk-ups than to single-story housing across the district. That's the gap a current structure count and building-height layer from satellite imagery is built to fill, sized to one district rather than a national mapping program.
If your district's housing stock has outgrown the last census count, Population Estimation turns a current structure count and building-height layer into the input the housing unit method is missing.